Explore how AI can assist with validating scanned assessment documents against defined assessment requirements. Working with a collection of 500+ assessment PDFs, it combines OCR, Python, vector search and large language models (LLMs) to extract, organise and interpret information from submitted documents.
Problem Statement
This hypothetical system aims to help assessment coordinators identify missing information, potential anomalies and responses that may require further review. OCR converts scanned documents into machine-readable text, Python processes and structures the extracted content, and a retrieval-augmented generation (RAG) pipeline uses embeddings and a vector database to locate relevant evidence. An LLM then interprets that evidence against specified assessment criteria and supports natural-language queries across the document collection.
A key focus is reliability and traceability. The system must distinguish between information that is genuinely absent and information that was missed or misinterpreted during extraction or retrieval. Responses should be grounded in the original documents, with evidence traceable to its source.
The project builds on an existing RAG pipeline and evaluates its performance through controlled experiments. By testing retrieval accuracy, information preservation and answer quality, it aims to establish where the approach works, where it fails, and what improvements are needed before it can support real assessment workflows.
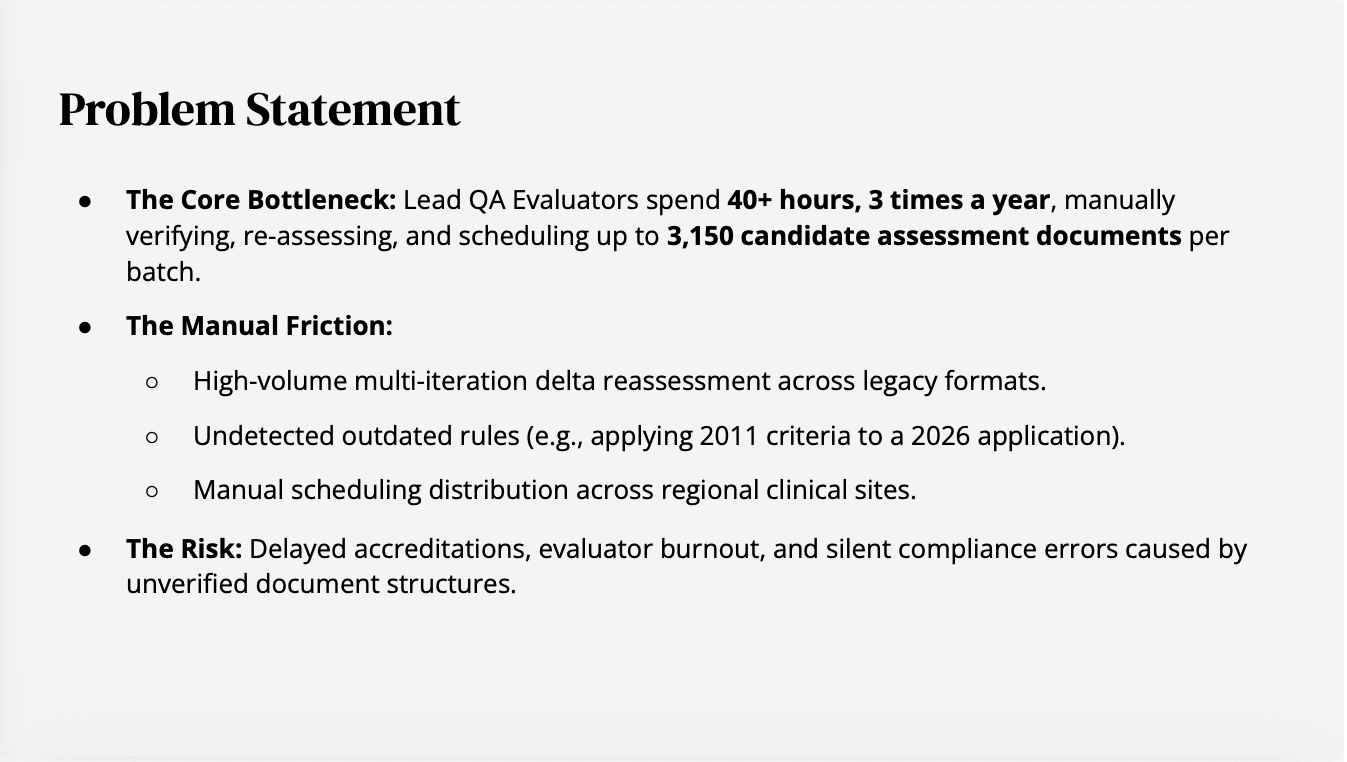 Figure 1: Project Prüfung - Problem Statement.
Disclaimer
This post describes technical concepts and lessons I explored during a learning project. Examples and datasets have been recreated or anonymised for demonstration purposes and do not represent any production system, customer data, or confidential information.
If this looks suspiciously familiar, that is probably because document retrieval problems are remarkably universal. Any resemblance to a particular organisation's problems is, conveniently, not the subject of this post.
The purpose of this post is educational: to explore the practical challenges of OCR, retrieval-augmented generation, evidence grounding, and evaluation. It is not intended to describe or disclose the internal systems, processes, or information of any former employer or organisation.